Update (17 Sep 2026): I thought we lost at 3 GB — turns out we’d won (as long as the cache is cold)
This article says, in one form or another, that ripgrep is faster at 3 GB. That was true while the file was in the OS page cache. Measured straight after
sudo purge— that is, opening a file you have not touched for a while — uvp is 2.6× faster even at 3 GB.
3 GB, fixed string rg uvp Cold (right after purge) 3.26 s 1.25 s (2.6×) Warm (again immediately) 0.33 s 1.01 s Six of seven search types behave the same way (uvp 1.6.3). The detail is in I thought we lost at 3 GB — turns out we’d won. Measured on a Mac (Apple M4 / 32 GB / external USB SSD); Windows and Linux — a low-powered laptop, under VMware — may behave differently. The figures below are unchanged (they were measured warm).
This is the run log of uv_cli_test4.sh, which checks every uvp command from the blog articles against rg / sort / uniq / sed / head / tail / gzip on real 3 GB, 10 GB and 50 GB files. What the commands mean and how to use them is covered in We shipped a uvp command and the CLI-to-UwView-Pro cheat sheet, so it is not repeated here.
Run log (complete, unedited)
 % ./uv_cli_test4.sh
# uvp commands from the articles, checked against the CLI (rg / sort / uniq / sed) — run 20260915-170224-uvp4

| Item | Value |
|---|---|
| OS | Darwin 25.3.0 arm64 |
| Machine | Apple M4 / 32GB |
| uvp | /usr/local/bin/uvp uvp 1.6.0 |
| ripgrep | /opt/homebrew/bin/rg (ripgrep 15.2.0) |
| sed | /usr/bin/sed (BSD sed) |
| Data | /Volumes/BIWIN/26work/UwViewData/osm |
| .uwvz | existing sidecar reused (built first if missing) |
| Hit limit | counted across all shards; rows whose first term can exceed 1,000,000 hits carry `-limit none` |
| Checks | search icase regex drill invert grepform context seq tally sortcnt sortval headtail sorthead outtxt outgz sedline uwvzonly extract cat exit1 regexnl exit2 limitn limitnone replace replacere |

== 3G: osm/japan-dv-ai  3032812644 bytes
  .uwvz present (251829224 bytes) → reusing it
  $ rg -n -F '東京' osm/japan-dv-ai
  $ uvp osm/japan-dv-ai '東京'
  ✅ search (literal)                   CLI     3.31 s  uvp     0.79 s  CLI/uvp=4.19 🟢            11274 hits  exit=0  .uwvz reused
  $ rg -n -i -F tokyo osm/japan-dv-ai
  $ uvp osm/japan-dv-ai tokyo -i
  ✅ ignore case -i                     CLI     0.53 s  uvp     0.64 s  CLI/uvp=1/1.21 🍊           2137 hits  exit=0  .uwvz reused
  $ rg -n 'v="(bus_stop|traffic_signals)"' osm/japan-dv-ai
  $ uvp osm/japan-dv-ai 'v="(bus_stop|traffic_signals)"' -E
  ✅ regex -E                           CLI     0.63 s  uvp     0.79 s  CLI/uvp=1/1.25 🍊          20620 hits  exit=0  .uwvz reused
  $ rg -n -F 'k="amenity"' osm/japan-dv-ai | rg -F 'v="parking"'
  $ uvp osm/japan-dv-ai 'k="amenity"' 'v="parking"' -limit none
  ✅ drill-down (2 terms)               CLI     0.46 s  uvp     1.30 s  CLI/uvp=1/2.83 🍊          94843 hits  exit=0  .uwvz reused
  $ rg -n -F 'k="amenity"' osm/japan-dv-ai | rg -v -F 'v="parking"'
  $ uvp osm/japan-dv-ai 'k="amenity"' 'v="parking"' -v -limit none
  ✅ exclude -v                         CLI     0.46 s  uvp     1.33 s  CLI/uvp=1/2.89 🍊          38373 hits  exit=0  .uwvz reused
  $ uvp osm/japan-dv-ai 'k="amenity"' -grep 'v="parking"' -limit none
  ✅ drill-down (-grep form)            CLI        - s  uvp     1.39 s  CLI/uvp=-                 94843 hits  exit=0  same result as the two-term form?
  $ uvp osm/japan-dv-ai 'k="amenity"' -C 3 'k="name"' -limit none
  ・ 2nd term within ±3 lines -C        CLI        - s  uvp     1.25 s  CLI/uvp=-                 14301 hits  exit=0  no single CLI command means this (rg -C only prints context)
  $ uvp osm/japan-dv-ai -seq 'k="amenity",k="name"' -limit none
  ・ order -seq                         CLI        - s  uvp     1.02 s  CLI/uvp=-                 37125 hits  exit=0  no CLI equivalent (needs an awk state machine)
  $ rg -N -o 'k="amenity" v="([^"]+)"' -r '$1' osm/japan-dv-ai | LC_ALL=C sort | uniq -c | sort -k1,1nr | head -20
  $ uvp osm/japan-dv-ai 'k="amenity"' -uniq 'v="([^"]+)"' -head 20 -limit none
  ✅ tally -uniq top 20                 CLI     0.45 s  uvp     0.76 s  CLI/uvp=1/1.69 🍊             20 hits  exit=0  values and counts compared as a set (sort|uniq -c|sort -rn|head)
  $ rg -N -o 'k="amenity" v="([^"]+)"' -r '$1' osm/japan-dv-ai | LC_ALL=C sort | uniq -c | sort -k1,1nr | head -20
  $ uvp osm/japan-dv-ai 'k="amenity"' -uniq 'v="([^"]+)"' -sort count -head 20 -limit none
  ✅ tally + -sort count                CLI     0.45 s  uvp     0.89 s  CLI/uvp=1/1.98 🍊             20 hits  exit=0  ties may order differently (compared as a set)
  $ rg -N -o 'k="amenity" v="([^"]+)"' -r '$1' osm/japan-dv-ai | LC_ALL=C sort | uniq -c | LC_ALL=C sort -k2 | head -20
  $ uvp osm/japan-dv-ai 'k="amenity"' -uniq 'v="([^"]+)"' -sort value -head 20 -limit none
  ✅ tally + -sort value                CLI     0.44 s  uvp     0.87 s  CLI/uvp=1/1.98 🍊             20 hits  exit=0  top 20 by value (compared in LC_ALL=C order)
  $ rg -n -F '東京' osm/japan-dv-ai | head -10
  $ uvp osm/japan-dv-ai '東京' -head 10
  ✅ first 10 -head                     CLI     0.05 s  uvp     0.74 s  CLI/uvp=1/14.80 🍊            10 hits  exit=0  rg stops after emitting 10 lines (early exit); the full-scan form is the next row (sort then head)
  $ rg -n -F '東京' osm/japan-dv-ai | tail -10
  $ uvp osm/japan-dv-ai '東京' -tail 10
  ✅ last 10 -tail                      CLI     0.34 s  uvp     0.83 s  CLI/uvp=1/2.44 🍊             10 hits  exit=0  rg | tail must scan everything to know the end (no early exit)
  $ rg -N -F '東京' osm/japan-dv-ai | LC_ALL=C sort | head -10
  $ uvp osm/japan-dv-ai '東京' -sort '^(.*)$' -head 10 --no-line-number
  ✅ sort then first 10                 CLI     0.29 s  uvp     0.70 s  CLI/uvp=1/2.41 🍊             10 hits  exit=0  same as rg | sort | head (LC_ALL=C, key = whole line)
  $ rg -n -F '東京' osm/japan-dv-ai > cli-test-results/20260915-170224-uvp4/3G/rg_out.txt
  $ uvp osm/japan-dv-ai '東京' -out cli-test-results/20260915-170224-uvp4/3G/uvp_out.txt
  ✅ -out (text)                        CLI     0.35 s  uvp     0.83 s  CLI/uvp=1/2.37 🍊          11274 hits  exit=0  the two written files compared
  $ rg -n -F '東京' osm/japan-dv-ai | gzip -6 > cli-test-results/20260915-170224-uvp4/3G/rg_out.txt.gz
  $ uvp osm/japan-dv-ai '東京' -out cli-test-results/20260915-170224-uvp4/3G/uvp_out.txt.gz
  ✅ -out (.gz)                         CLI     0.36 s  uvp     0.84 s  CLI/uvp=1/2.33 🍊          11274 hits  exit=0  decompressed, then contents compared
  $ sed -n '/東京/p' osm/japan-dv-ai
  $ uvp osm/japan-dv-ai '東京' --no-line-number
  ✅ lines only ↔ sed -n p              CLI     9.61 s  uvp     0.75 s  CLI/uvp=12.81 🟢           11274 hits  exit=0  compared against sed's extraction, body only (no line numbers)
  $ uvp osm/japan-dv-ai.uwvz '東京'
  ✅ search the .uwvz alone             CLI        - s  uvp     0.74 s  CLI/uvp=-                 11274 hits  exit=0  searched from the .uwvz without touching the original
  $ uvp osm/japan-dv-ai.uwvz -extract -out cli-test-results/20260915-170224-uvp4/3G/extracted
  ✅ -extract (byte-identical)          CLI        - s  uvp     3.62 s  CLI/uvp=-                     - hits  exit=0  free feature; cmp against the original
  $ uvp cat osm/japan-dv-ai
  ✅ cat (raw text)                     CLI        - s  uvp     3.65 s  CLI/uvp=-                     - hits  exit=0  cmp against the original file
  $ uvp osm/japan-dv-ai NO_SUCH_WORD_ZZ9
  ✅ no match → exit 1                  CLI        - s  uvp     0.66 s  CLI/uvp=-                     0 hits  exit=1  grep-compatible (0 = found, 1 = not found)
  $ rg -n '[0-9]{3}-[0-9]{4}"' osm/japan-dv-ai
  $ uvp osm/japan-dv-ai '[0-9]{3}-[0-9]{4}"' -E
  ✅ regex -E (no literal)              CLI     2.46 s  uvp     1.08 s  CLI/uvp=2.28 🟢            14951 hits  exit=0  a pattern with no required literal = no prefilter; compare with the regex row
  $ rg -n -F 'k="building"' osm/japan-dv-ai
  $ uvp osm/japan-dv-ai 'k="building"'
  ✅ default limit (exit 2 / all hits)  CLI     0.83 s  uvp     0.59 s  CLI/uvp=1.41 🟢          1000000 hits  exit=2  cut off at the 1000000-hit limit (rg found 5747705); exactly the limit, in line order, a subset of rg
  $ uvp osm/japan-dv-ai '東京' -limit 1000
  ✅ -limit 1000                        CLI        - s  uvp     0.32 s  CLI/uvp=-                  1000 hits  exit=2  cut off at the 1000-hit limit (rg found 11274); exactly the limit, in line order, a subset of rg
  $ uvp osm/japan-dv-ai 'k="building"' -limit none
  ✅ -limit none (all hits)             CLI     0.83 s  uvp     2.80 s  CLI/uvp=1/3.37 🍊        5747705 hits  exit=0  returns everything and matches rg (5747705 hits)?

== 10G: osm/japan-dv-ac  10255315281 bytes
  .uwvz present (1164605577 bytes) → reusing it
  $ rg -n -F '東京' osm/japan-dv-ac
  $ uvp osm/japan-dv-ac '東京'
  ✅ search (literal)                   CLI    11.19 s  uvp     1.87 s  CLI/uvp=5.98 🟢            11393 hits  exit=0  .uwvz reused
  $ rg -n -i -F tokyo osm/japan-dv-ac
  $ uvp osm/japan-dv-ac tokyo -i
  ✅ ignore case -i                     CLI    11.13 s  uvp     1.83 s  CLI/uvp=6.08 🟢             1286 hits  exit=0  .uwvz reused
  $ rg -n 'v="(bus_stop|traffic_signals)"' osm/japan-dv-ac
  $ uvp osm/japan-dv-ac 'v="(bus_stop|traffic_signals)"' -E
  ✅ regex -E                           CLI    11.19 s  uvp     2.00 s  CLI/uvp=5.59 🟢           167126 hits  exit=0  .uwvz reused
  $ rg -n -F 'k="amenity"' osm/japan-dv-ac | rg -F 'v="parking"'
  $ uvp osm/japan-dv-ac 'k="amenity"' 'v="parking"' -limit none
  ✅ drill-down (2 terms)               CLI    11.14 s  uvp     3.75 s  CLI/uvp=2.97 🟢             2659 hits  exit=0  .uwvz reused
  $ rg -n -F 'k="amenity"' osm/japan-dv-ac | rg -v -F 'v="parking"'
  $ uvp osm/japan-dv-ac 'k="amenity"' 'v="parking"' -v -limit none
  ✅ exclude -v                         CLI    11.03 s  uvp     3.96 s  CLI/uvp=2.79 🟢           168887 hits  exit=0  .uwvz reused
  $ uvp osm/japan-dv-ac 'k="amenity"' -grep 'v="parking"' -limit none
  ✅ drill-down (-grep form)            CLI        - s  uvp     3.75 s  CLI/uvp=-                  2659 hits  exit=0  same result as the two-term form?
  $ uvp osm/japan-dv-ac 'k="amenity"' -C 3 'k="name"' -limit none
  ・ 2nd term within ±3 lines -C        CLI        - s  uvp     3.90 s  CLI/uvp=-                 66778 hits  exit=0  no single CLI command means this (rg -C only prints context)
  $ uvp osm/japan-dv-ac -seq 'k="amenity",k="name"' -limit none
  ・ order -seq                         CLI        - s  uvp     2.97 s  CLI/uvp=-                118625 hits  exit=0  no CLI equivalent (needs an awk state machine)
  $ rg -N -o 'k="amenity" v="([^"]+)"' -r '$1' osm/japan-dv-ac | LC_ALL=C sort | uniq -c | sort -k1,1nr | head -20
  $ uvp osm/japan-dv-ac 'k="amenity"' -uniq 'v="([^"]+)"' -head 20 -limit none
  ✅ tally -uniq top 20                 CLI    11.05 s  uvp     2.15 s  CLI/uvp=5.14 🟢               20 hits  exit=0  values and counts compared as a set (sort|uniq -c|sort -rn|head)
  $ rg -N -o 'k="amenity" v="([^"]+)"' -r '$1' osm/japan-dv-ac | LC_ALL=C sort | uniq -c | sort -k1,1nr | head -20
  $ uvp osm/japan-dv-ac 'k="amenity"' -uniq 'v="([^"]+)"' -sort count -head 20 -limit none
  ✅ tally + -sort count                CLI    11.07 s  uvp     2.00 s  CLI/uvp=5.54 🟢               20 hits  exit=0  ties may order differently (compared as a set)
  $ rg -N -o 'k="amenity" v="([^"]+)"' -r '$1' osm/japan-dv-ac | LC_ALL=C sort | uniq -c | LC_ALL=C sort -k2 | head -20
  $ uvp osm/japan-dv-ac 'k="amenity"' -uniq 'v="([^"]+)"' -sort value -head 20 -limit none
  ✅ tally + -sort value                CLI    11.07 s  uvp     2.15 s  CLI/uvp=5.15 🟢               20 hits  exit=0  top 20 by value (compared in LC_ALL=C order)
  $ rg -n -F '東京' osm/japan-dv-ac | head -10
  $ uvp osm/japan-dv-ac '東京' -head 10
  ✅ first 10 -head                     CLI     0.48 s  uvp     1.50 s  CLI/uvp=1/3.12 🍊             10 hits  exit=0  rg stops after emitting 10 lines (early exit); the full-scan form is the next row (sort then head)
  $ rg -n -F '東京' osm/japan-dv-ac | tail -10
  $ uvp osm/japan-dv-ac '東京' -tail 10
  ✅ last 10 -tail                      CLI    10.61 s  uvp     1.95 s  CLI/uvp=5.44 🟢               10 hits  exit=0  rg | tail must scan everything to know the end (no early exit)
  $ rg -N -F '東京' osm/japan-dv-ac | LC_ALL=C sort | head -10
  $ uvp osm/japan-dv-ac '東京' -sort '^(.*)$' -head 10 --no-line-number
  ✅ sort then first 10                 CLI    11.98 s  uvp     1.99 s  CLI/uvp=6.02 🟢               10 hits  exit=0  same as rg | sort | head (LC_ALL=C, key = whole line)
  $ rg -n -F '東京' osm/japan-dv-ac > cli-test-results/20260915-170224-uvp4/10G/rg_out.txt
  $ uvp osm/japan-dv-ac '東京' -out cli-test-results/20260915-170224-uvp4/10G/uvp_out.txt
  ✅ -out (text)                        CLI    10.98 s  uvp     2.00 s  CLI/uvp=5.49 🟢            11393 hits  exit=0  the two written files compared
  $ rg -n -F '東京' osm/japan-dv-ac | gzip -6 > cli-test-results/20260915-170224-uvp4/10G/rg_out.txt.gz
  $ uvp osm/japan-dv-ac '東京' -out cli-test-results/20260915-170224-uvp4/10G/uvp_out.txt.gz
  ✅ -out (.gz)                         CLI    11.06 s  uvp     1.86 s  CLI/uvp=5.95 🟢            11393 hits  exit=0  decompressed, then contents compared
  $ sed -n '/東京/p' osm/japan-dv-ac
  $ uvp osm/japan-dv-ac '東京' --no-line-number
  ✅ lines only ↔ sed -n p              CLI    14.01 s  uvp     1.81 s  CLI/uvp=7.74 🟢            11393 hits  exit=0  compared against sed's extraction, body only (no line numbers)
  $ uvp osm/japan-dv-ac.uwvz '東京'
  ✅ search the .uwvz alone             CLI        - s  uvp     1.55 s  CLI/uvp=-                 11393 hits  exit=0  searched from the .uwvz without touching the original
  $ uvp osm/japan-dv-ac.uwvz -extract -out cli-test-results/20260915-170224-uvp4/10G/extracted
  ✅ -extract (byte-identical)          CLI        - s  uvp    12.93 s  CLI/uvp=-                     - hits  exit=0  free feature; cmp against the original
  $ uvp cat osm/japan-dv-ac
  ✅ cat (raw text)                     CLI        - s  uvp    38.47 s  CLI/uvp=-                     - hits  exit=0  cmp against the original file
  $ uvp osm/japan-dv-ac NO_SUCH_WORD_ZZ9
  ✅ no match → exit 1                  CLI        - s  uvp     1.95 s  CLI/uvp=-                     0 hits  exit=1  grep-compatible (0 = found, 1 = not found)
  $ rg -n '[0-9]{3}-[0-9]{4}"' osm/japan-dv-ac
  $ uvp osm/japan-dv-ac '[0-9]{3}-[0-9]{4}"' -E
  ✅ regex -E (no literal)              CLI    14.38 s  uvp     2.43 s  CLI/uvp=5.92 🟢            24988 hits  exit=0  a pattern with no required literal = no prefilter; compare with the regex row
  $ rg -n -F 'k="building"' osm/japan-dv-ac
  $ uvp osm/japan-dv-ac 'k="building"'
  ✅ default limit (exit 2 / all hits)  CLI    11.13 s  uvp     1.92 s  CLI/uvp=5.80 🟢              861 hits  exit=0  limit (?) not reached, all hits returned (same 861 as rg)
  $ uvp osm/japan-dv-ac '東京' -limit 1000
  ✅ -limit 1000                        CLI        - s  uvp     0.63 s  CLI/uvp=-                  1000 hits  exit=2  cut off at the 1000-hit limit (rg found 11393); exactly the limit, in line order, a subset of rg
  $ uvp osm/japan-dv-ac 'k="building"' -limit none
  ✅ -limit none (all hits)             CLI    11.13 s  uvp     1.47 s  CLI/uvp=7.57 🟢              861 hits  exit=0  returns everything and matches rg (861 hits)?

== 50G: osm/japan-latest.osm  51254526392 bytes
  .uwvz present (5737517251 bytes) → reusing it
  $ rg -n -F '東京' osm/japan-latest.osm
  $ uvp osm/japan-latest.osm '東京'
  ✅ search (literal)                   CLI    55.66 s  uvp     7.15 s  CLI/uvp=7.78 🟢            94979 hits  exit=0  .uwvz reused
  $ rg -n -i -F tokyo osm/japan-latest.osm
  $ uvp osm/japan-latest.osm tokyo -i
  ✅ ignore case -i                     CLI    56.26 s  uvp     7.18 s  CLI/uvp=7.84 🟢            14355 hits  exit=0  .uwvz reused
  $ rg -n 'v="(bus_stop|traffic_signals)"' osm/japan-latest.osm
  $ uvp osm/japan-latest.osm 'v="(bus_stop|traffic_signals)"' -E
  ✅ regex -E                           CLI    55.70 s  uvp     7.75 s  CLI/uvp=7.19 🟢           602805 hits  exit=0  .uwvz reused
  $ rg -n -F 'k="amenity"' osm/japan-latest.osm | rg -F 'v="parking"'
  $ uvp osm/japan-latest.osm 'k="amenity"' 'v="parking"' -limit none
  ✅ drill-down (2 terms)               CLI    55.33 s  uvp    21.48 s  CLI/uvp=2.58 🟢           460467 hits  exit=0  .uwvz reused
  $ rg -n -F 'k="amenity"' osm/japan-latest.osm | rg -v -F 'v="parking"'
  $ uvp osm/japan-latest.osm 'k="amenity"' 'v="parking"' -v -limit none
  ✅ exclude -v                         CLI    55.35 s  uvp    21.10 s  CLI/uvp=2.62 🟢           935987 hits  exit=0  .uwvz reused
  $ uvp osm/japan-latest.osm 'k="amenity"' -grep 'v="parking"' -limit none
  ✅ drill-down (-grep form)            CLI        - s  uvp    20.34 s  CLI/uvp=-                460467 hits  exit=0  same result as the two-term form?
  $ uvp osm/japan-latest.osm 'k="amenity"' -C 3 'k="name"' -limit none
  ・ 2nd term within ±3 lines -C        CLI        - s  uvp    19.88 s  CLI/uvp=-                544212 hits  exit=0  no single CLI command means this (rg -C only prints context)
  $ uvp osm/japan-latest.osm -seq 'k="amenity",k="name"' -limit none
  ・ order -seq                         CLI        - s  uvp    13.46 s  CLI/uvp=-                846622 hits  exit=0  no CLI equivalent (needs an awk state machine)
  $ rg -N -o 'k="amenity" v="([^"]+)"' -r '$1' osm/japan-latest.osm | LC_ALL=C sort | uniq -c | sort -k1,1nr | head -20
  $ uvp osm/japan-latest.osm 'k="amenity"' -uniq 'v="([^"]+)"' -head 20 -limit none
  ✅ tally -uniq top 20                 CLI    55.40 s  uvp     8.33 s  CLI/uvp=6.65 🟢               20 hits  exit=0  values and counts compared as a set (sort|uniq -c|sort -rn|head)
  $ rg -N -o 'k="amenity" v="([^"]+)"' -r '$1' osm/japan-latest.osm | LC_ALL=C sort | uniq -c | sort -k1,1nr | head -20
  $ uvp osm/japan-latest.osm 'k="amenity"' -uniq 'v="([^"]+)"' -sort count -head 20 -limit none
  ✅ tally + -sort count                CLI    55.25 s  uvp     8.94 s  CLI/uvp=6.18 🟢               20 hits  exit=0  ties may order differently (compared as a set)
  $ rg -N -o 'k="amenity" v="([^"]+)"' -r '$1' osm/japan-latest.osm | LC_ALL=C sort | uniq -c | LC_ALL=C sort -k2 | head -20
  $ uvp osm/japan-latest.osm 'k="amenity"' -uniq 'v="([^"]+)"' -sort value -head 20 -limit none
  ✅ tally + -sort value                CLI    55.28 s  uvp     8.42 s  CLI/uvp=6.57 🟢               20 hits  exit=0  top 20 by value (compared in LC_ALL=C order)
  $ rg -n -F '東京' osm/japan-latest.osm | head -10
  $ uvp osm/japan-latest.osm '東京' -head 10
  ✅ first 10 -head                     CLI     0.16 s  uvp     6.74 s  CLI/uvp=1/42.12 🍊            10 hits  exit=0  rg stops after emitting 10 lines (early exit); the full-scan form is the next row (sort then head)
  $ rg -n -F '東京' osm/japan-latest.osm | tail -10
  $ uvp osm/japan-latest.osm '東京' -tail 10
  ✅ last 10 -tail                      CLI    55.13 s  uvp     8.10 s  CLI/uvp=6.81 🟢               10 hits  exit=0  rg | tail must scan everything to know the end (no early exit)
  $ rg -N -F '東京' osm/japan-latest.osm | LC_ALL=C sort | head -10
  $ uvp osm/japan-latest.osm '東京' -sort '^(.*)$' -head 10 --no-line-number
  ✅ sort then first 10                 CLI    55.26 s  uvp     7.22 s  CLI/uvp=7.65 🟢               10 hits  exit=0  same as rg | sort | head (LC_ALL=C, key = whole line)
  $ rg -n -F '東京' osm/japan-latest.osm > cli-test-results/20260915-170224-uvp4/50G/rg_out.txt
  $ uvp osm/japan-latest.osm '東京' -out cli-test-results/20260915-170224-uvp4/50G/uvp_out.txt
  ✅ -out (text)                        CLI    55.90 s  uvp     7.60 s  CLI/uvp=7.36 🟢            94979 hits  exit=0  the two written files compared
  $ rg -n -F '東京' osm/japan-latest.osm | gzip -6 > cli-test-results/20260915-170224-uvp4/50G/rg_out.txt.gz
  $ uvp osm/japan-latest.osm '東京' -out cli-test-results/20260915-170224-uvp4/50G/uvp_out.txt.gz
  ✅ -out (.gz)                         CLI    55.95 s  uvp     7.28 s  CLI/uvp=7.69 🟢            94979 hits  exit=0  decompressed, then contents compared
  $ sed -n '/東京/p' osm/japan-latest.osm
  $ uvp osm/japan-latest.osm '東京' --no-line-number
  ✅ lines only ↔ sed -n p              CLI   105.75 s  uvp    12.31 s  CLI/uvp=8.59 🟢            94979 hits  exit=0  compared against sed's extraction, body only (no line numbers)
  $ uvp osm/japan-latest.osm.uwvz '東京'
  ✅ search the .uwvz alone             CLI        - s  uvp     7.90 s  CLI/uvp=-                 94979 hits  exit=0  searched from the .uwvz without touching the original
  $ uvp osm/japan-latest.osm.uwvz -extract -out cli-test-results/20260915-170224-uvp4/50G/extracted
  ✅ -extract (byte-identical)          CLI        - s  uvp    61.76 s  CLI/uvp=-                     - hits  exit=0  free feature; cmp against the original
  $ uvp cat osm/japan-latest.osm
  ✅ cat (raw text)                     CLI        - s  uvp   243.12 s  CLI/uvp=-                     - hits  exit=0  cmp against the original file
  $ uvp osm/japan-latest.osm NO_SUCH_WORD_ZZ9
  ✅ no match → exit 1                  CLI        - s  uvp     7.03 s  CLI/uvp=-                     0 hits  exit=1  grep-compatible (0 = found, 1 = not found)
  $ rg -n '[0-9]{3}-[0-9]{4}"' osm/japan-latest.osm
  $ uvp osm/japan-latest.osm '[0-9]{3}-[0-9]{4}"' -E
  ✅ regex -E (no literal)              CLI    67.60 s  uvp    12.88 s  CLI/uvp=5.25 🟢           224915 hits  exit=0  a pattern with no required literal = no prefilter; compare with the regex row
  $ rg -n -F 'k="building"' osm/japan-latest.osm
  $ uvp osm/japan-latest.osm 'k="building"'
  ✅ default limit (exit 2 / all hits)  CLI    60.35 s  uvp     1.24 s  CLI/uvp=48.67 🟢         1000000 hits  exit=2  cut off at the 1000000-hit limit (rg found 29114490); exactly the limit, in line order, a subset of rg
  $ uvp osm/japan-latest.osm '東京' -limit 1000
  ✅ -limit 1000                        CLI        - s  uvp     0.52 s  CLI/uvp=-                  1000 hits  exit=2  cut off at the 1000-hit limit (rg found 94979); exactly the limit, in line order, a subset of rg
  $ uvp osm/japan-latest.osm 'k="building"' -limit none
  ✅ -limit none (all hits)             CLI    60.35 s  uvp    27.12 s  CLI/uvp=2.23 🟢         29114490 hits  exit=0  returns everything and matches rg (29114490 hits)?

== replace 3G: osm/japan-dv-ai
  $ uvp osm/japan-dv-ai '東京' -replace TOKYO -out cli-test-results/20260915-170224-uvp4/3G/uvp_rep.txt
  $ rg -N -F --passthru '東京' -r TOKYO osm/japan-dv-ai > cli-test-results/20260915-170224-uvp4/3G/rg_rep.txt
  ✅ replace -replace ↔ rg --passthru   CLI     7.06 s  uvp     4.57 s  CLI/uvp=1.54 🟢           11,361 hits  exit=0  whole output compared byte for byte (count = replaced occurrences)
  $ LC_ALL=C sed 's/東京/TOKYO/g' osm/japan-dv-ai > cli-test-results/20260915-170224-uvp4/3G/sed_rep.txt
  ✅ replace -replace ↔ sed 's/A/B/g'   CLI    14.94 s  uvp     4.57 s  CLI/uvp=3.27 🟢           11,361 hits  exit=0  whole output compared byte for byte
  $ uvp osm/japan-dv-ai 'v="(bus_stop|traffic_signals)"' -E -replace 'v="X_$1"' -out cli-test-results/20260915-170224-uvp4/3G/uvp_repre.txt
  $ rg -N --passthru 'v="(bus_stop|traffic_signals)"' -r 'v="X_$1"' osm/japan-dv-ai > cli-test-results/20260915-170224-uvp4/3G/rg_repre.txt
  ✅ replace -E $1 ↔ rg --passthru      CLI     4.97 s  uvp     4.17 s  CLI/uvp=1.19 🟢           20,620 hits  exit=0  whole output compared byte for byte (count = replaced occurrences)
  $ LC_ALL=C sed -E 's/v="(bus_stop|traffic_signals)"/v="X_\1"/g' osm/japan-dv-ai > cli-test-results/20260915-170224-uvp4/3G/sed_repre.txt
  ✅ replace -E $1 ↔ sed -E             CLI    24.81 s  uvp     4.17 s  CLI/uvp=5.95 🟢           20,620 hits  exit=0  whole output compared byte for byte

== replace 10G: osm/japan-dv-ac
  $ uvp osm/japan-dv-ac '東京' -replace TOKYO -out cli-test-results/20260915-170224-uvp4/10G/uvp_rep.txt
  $ rg -N -F --passthru '東京' -r TOKYO osm/japan-dv-ac > cli-test-results/20260915-170224-uvp4/10G/rg_rep.txt
  ✅ replace -replace ↔ rg --passthru   CLI    26.89 s  uvp    13.47 s  CLI/uvp=2.00 🟢           11,445 hits  exit=0  whole output compared byte for byte (count = replaced occurrences)
  $ LC_ALL=C sed 's/東京/TOKYO/g' osm/japan-dv-ac > cli-test-results/20260915-170224-uvp4/10G/sed_rep.txt
  ✅ replace -replace ↔ sed 's/A/B/g'   CLI    26.51 s  uvp    13.47 s  CLI/uvp=1.97 🟢           11,445 hits  exit=0  whole output compared byte for byte
  $ uvp osm/japan-dv-ac 'v="(bus_stop|traffic_signals)"' -E -replace 'v="X_$1"' -out cli-test-results/20260915-170224-uvp4/10G/uvp_repre.txt
  $ rg -N --passthru 'v="(bus_stop|traffic_signals)"' -r 'v="X_$1"' osm/japan-dv-ac > cli-test-results/20260915-170224-uvp4/10G/rg_repre.txt
  ✅ replace -E $1 ↔ rg --passthru      CLI    26.80 s  uvp    14.08 s  CLI/uvp=1.90 🟢          167,126 hits  exit=0  whole output compared byte for byte (count = replaced occurrences)
  $ LC_ALL=C sed -E 's/v="(bus_stop|traffic_signals)"/v="X_\1"/g' osm/japan-dv-ac > cli-test-results/20260915-170224-uvp4/10G/sed_repre.txt
  ✅ replace -E $1 ↔ sed -E             CLI    78.36 s  uvp    14.08 s  CLI/uvp=5.57 🟢          167,126 hits  exit=0  whole output compared byte for byte

== replace 50G: osm/japan-latest.osm
  $ uvp osm/japan-latest.osm '東京' -replace TOKYO -out cli-test-results/20260915-170224-uvp4/50G/uvp_rep.txt
  $ rg -N -F --passthru '東京' -r TOKYO osm/japan-latest.osm > cli-test-results/20260915-170224-uvp4/50G/rg_rep.txt
  ✅ replace -replace ↔ rg --passthru   CLI   146.65 s  uvp    69.75 s  CLI/uvp=2.10 🟢           95,328 hits  exit=0  whole output compared byte for byte (count = replaced occurrences)
  $ LC_ALL=C sed 's/東京/TOKYO/g' osm/japan-latest.osm > cli-test-results/20260915-170224-uvp4/50G/sed_rep.txt
  ✅ replace -replace ↔ sed 's/A/B/g'   CLI   187.74 s  uvp    69.75 s  CLI/uvp=2.69 🟢           95,328 hits  exit=0  whole output compared byte for byte
  $ uvp osm/japan-latest.osm 'v="(bus_stop|traffic_signals)"' -E -replace 'v="X_$1"' -out cli-test-results/20260915-170224-uvp4/50G/uvp_repre.txt
  $ rg -N --passthru 'v="(bus_stop|traffic_signals)"' -r 'v="X_$1"' osm/japan-latest.osm > cli-test-results/20260915-170224-uvp4/50G/rg_repre.txt
  ✅ replace -E $1 ↔ rg --passthru      CLI   132.74 s  uvp    69.95 s  CLI/uvp=1.90 🟢          602,805 hits  exit=0  whole output compared byte for byte (count = replaced occurrences)
  $ LC_ALL=C sed -E 's/v="(bus_stop|traffic_signals)"/v="X_\1"/g' osm/japan-latest.osm > cli-test-results/20260915-170224-uvp4/50G/sed_repre.txt
  ✅ replace -E $1 ↔ sed -E             CLI   405.52 s  uvp    69.95 s  CLI/uvp=5.80 🟢          602,805 hits  exit=0  whole output compared byte for byte

================================================================
matched: 81    mismatched: 0    reference only: 6
Report: /Volumes/BIWIN/26work/UwViewData/cli-test-results/20260915-170224-uvp4/summary.md
y4u@MacBook-Air UwViewData % uvp --help
Usage:
  uvp <file> <term> [stages…] [options]          investigate (flag syntax)
  uvp <file> '<term> | sort … | uniq …'          investigate (quoted pipe syntax, same meaning)
  uvp convert <file> [-out x.uwvz]               build the .uwvz
  uvp cat <file> [-out …]                        print the text
  uvp <file.uwvz> -extract [txt|gz|zip]          restore the original (free)
  uvp <file> <term> -replace <text>              print the whole text with matches replaced (sed 's/A/B/g'; Edit license)
  uvp -open [<file>]                             launch the app (and open the file if given)

Stages (run in the order written):
  <term> / -grep <term>  search. Later searches look only within ±N of the previous stage (drill-down)
    -i ignore case  -E regex  -w whole word  -v exclude (2nd stage on)  -C N context lines
  -uniq <key>            tally (key = first capture group of a regex)
  -sort <key>            sort (lines by key / after -uniq by count or value)
  -seq a,b,c             flows where a→b→c appear in that order
  -head N / -tail N      first / last N

Options:
  -out <file>            output file (.gz / .zip are compressed; anything else is text)
  -limit N               max hits kept per search (default: the app setting, initially 1,000,000;
                         0 or none = unlimited. Memory grows with the hit count, so write large results with -out)
  -replace <text>        print the whole text with every match of the term (-i -E -w allowed) replaced.
                         The file itself is not changed. The text is literal; with -E, $1 etc. insert groups ($$ = $)
  --force                overwrite an existing output file
  --no-line-number       omit line numbers
  --csv / --json         format for tally results
  -open                  at the start: run in the app / at the end: run, then also open in the app

Exit codes: 0=found 1=not found 2=error
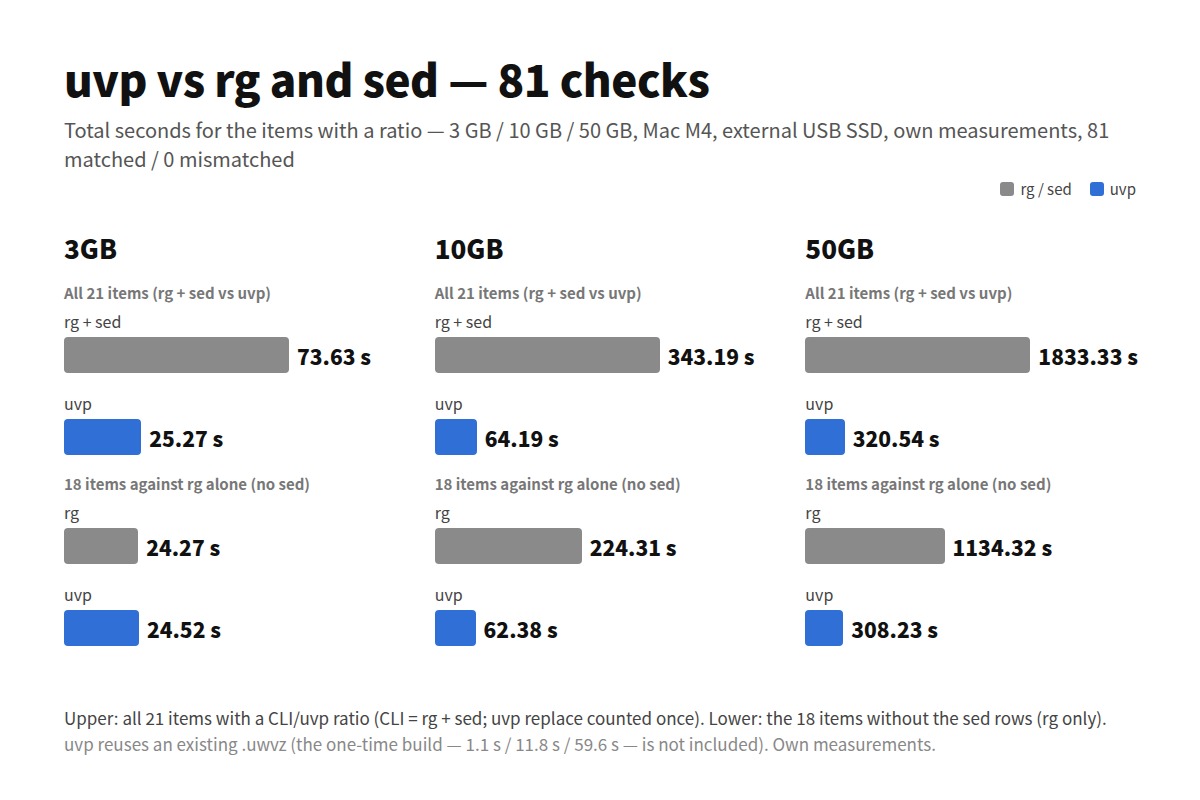
Totals for the items with a ratio (the header chart)
Only the items where CLI/uvp= shows a number — a CLI command does the same job and both timings exist — are collected and summed per size. The four replace rows check the same uvp run against both rg and sed, so uvp’s seconds are counted once.
All 21 items (17 search / tally / output + 4 replace; CLI = rg and sed)
| Size | CLI total | uvp total | CLI/uvp |
|---|---|---|---|
| 3 GB | 73.63 s | 25.27 s | 2.9 |
| 10 GB | 343.19 s | 64.19 s | 5.3 |
| 50 GB | 1,833.33 s | 320.54 s | 5.7 |
18 items without the sed rows (CLI = rg only)
| Size | rg total | uvp total | rg/uvp |
|---|---|---|---|
| 3 GB | 24.27 s | 24.52 s | 1.0 |
| 10 GB | 224.31 s | 62.38 s | 3.6 |
| 50 GB | 1,134.32 s | 308.23 s | 3.7 |
The upper row of the header image is the 21 items, the lower row the 18 rg-only items. All uvp figures reuse an existing .uwvz; the one-time .uwvz build (1.1 s at 3 GB, 11.8 s at 10 GB, 59.6 s at 50 GB) is not included.
Items with no rg / uvp ratio
The items where the log shows CLI/uvp=-. There are 8 per size.
| Item | Reason (as noted in the log) |
|---|---|
drill-down, -grep syntax |
Checks that it gives the same result as writing the two terms in a row; the CLI side is timed on the two-term row |
second term within ±3 lines, -C |
No single CLI command with the same meaning (rg -C only prints context) |
sequence, -seq |
No CLI equivalent (would need an awk state machine) |
search the .uwvz alone |
Searches the .uwvz without reading the original; no CLI equivalent |
-extract |
Only cmp against the original; not timed against gzip -dc because the formats differ |
cat |
Only cmp against the original |
| not found → exit 1 | Exit-code check |
-limit 1000 |
uvp-specific hit limit |
The breakdown — 81 matched, 0 mismatched, 6 reference — is the summary line at the end of the log.
Related
- We shipped a uvp command — the same answers as ripgrep, 7× faster at 10 GB. And at 3 GB too, if the cache is cold
- Keep it as .uwvz instead of gzip — 1/9 the size, searchable in 7 seconds, and free to restore
- Five Questions Against 258 GB and 4.5 Billion Lines — Where grep Loses to a GUI
- grep, uniq -c and sed in a GUI — the CLI-to-UwView-Pro Cheat Sheet
- Benchmarks — huge-file tools compared